Storage Tiering and How Different Data Can Use Different Storage Media
A company can have terabytes or even petabytes of data without needing every file to sit on the fastest storage available. That sounds obvious until you consider what is actually stored. A database serving customers throughout the day may need very fast access. A set of project files might be opened frequently for several weeks and then rarely touched. Old backups may need to be retained for years but almost never retrieved. Treating all three categories identically would either waste money or create unnecessary performance limitations.
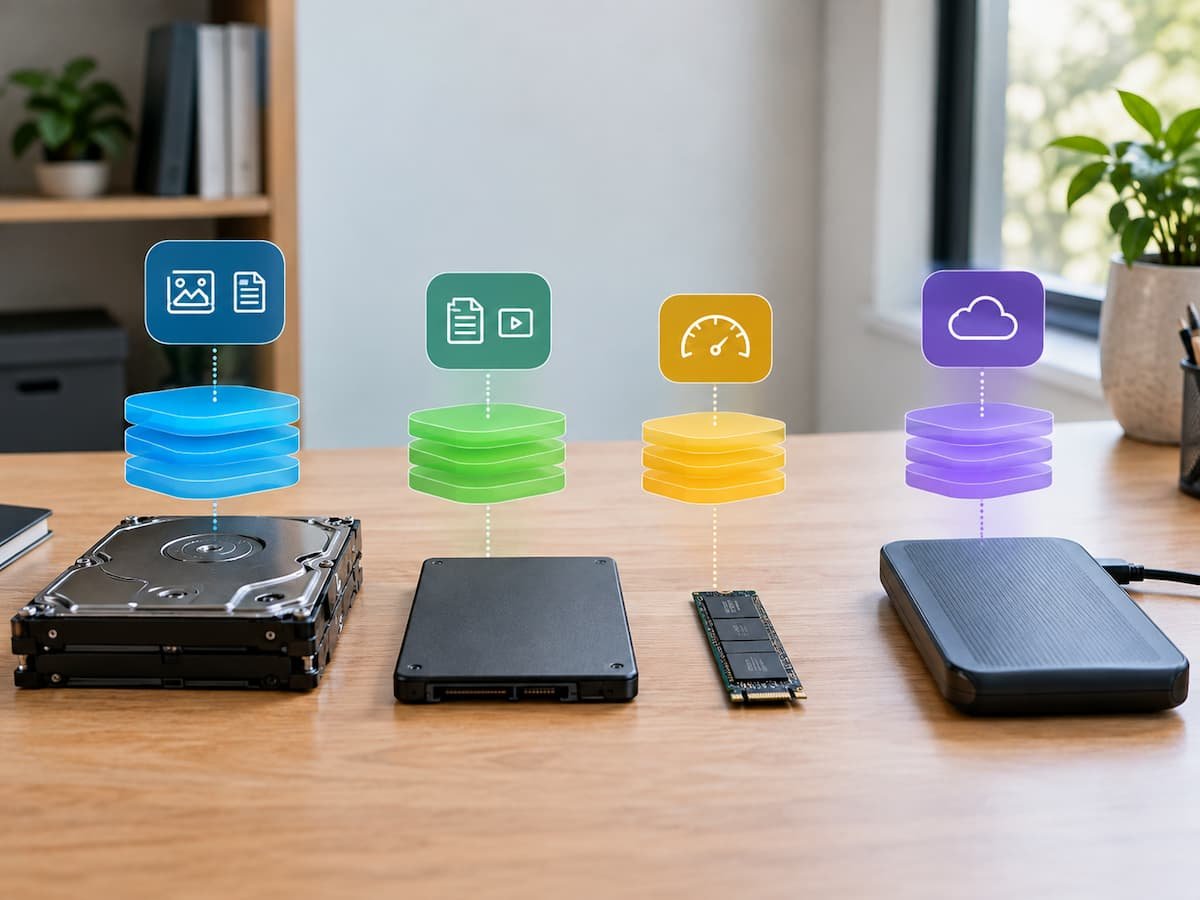
Storage tiering is the practice of placing data on different types or levels of storage according to its needs.
Instead of asking, “What is the fastest storage we can buy?”, a tiered storage strategy asks a more useful question:
Which data actually needs fast storage, and which data can live somewhere cheaper or slower?
That change in perspective is the foundation of storage tiering.
Think about the data before thinking about the hardware.
Imagine a business has 100 TB of stored information.
It might contain:
- Frequently accessed databases
- Current customer files
- Active video projects
- Older documents
- Completed projects
- System backups
- Long-term archives
- Temporary processing data
These datasets do not have identical requirements. A database handling frequent transactions may be sensitive to latency. An archive containing records that are opened twice a year has very different requirements.
This creates a natural hierarchy.
| Data behaviour | Possible storage approach |
|---|---|
| Constantly accessed | High-performance SSD/NVMe |
| Frequently accessed | SSD or fast HDD depending on workload |
| Occasionally accessed | HDD or capacity-orientated storage |
| Rarely accessed | Lower-cost capacity or archival tier |
| Long-term archive | Specialised archival storage |
The exact implementation varies between systems. Storage tiering is not a fixed list of hardware categories.
The important principle is matching storage characteristics to data behaviour.
The four questions that determine where data belongs
A useful way to understand storage tiering is to ignore the storage devices initially and examine the data itself.
For each dataset, ask four questions.
1. How often is it accessed?
A file opened hundreds of times a day has a different storage requirement from one opened once every two years.
Access frequency is sometimes described using terms such as:
- Hot data
- Warm data
- Cold data
- Archive data
These labels are conceptual rather than universal technical standards.
- Hot data generally means information that is actively being used.
- Warm data is still useful and may be accessed regularly, but it does not necessarily require the highest performance.
- Cold data is accessed infrequently.
- Archive data is generally retained primarily for long-term reference, compliance, historical value, or recovery.
The same file can move between these categories as its usefulness changes.
2. How quickly does it need to respond?
- Frequency is only half the story.
- Suppose two datasets are each accessed once per hour.
- One might be part of an interactive application where users expect an immediate response. The other might be a background report that can take several minutes to process.
- Their access frequency is similar, but their latency requirements are not.
- This is why storage tiering should consider performance requirements, not simply how often a file is opened.
3. How much does the data cost to replace?
- Some information is easy to regenerate.
- Temporary application cache files, for example, may be recreated by the software.
- Other data may represent years of work.
- Losing a cache is inconvenient. Losing an irreplaceable archive is a fundamentally different problem.
- Storage decisions therefore need to consider the value and recoverability of the information, not just its size.
4. How long must the data remain available?
- A dataset may become rarely accessed without becoming disposable.
- Old financial records, completed projects, historical research data, or backups may still need to be retained.
- This creates an important distinction:
- Infrequently accessed does not mean unimportant.
- A cold-storage decision should not be interpreted as permission to forget about the data.
What the tiers can look like in practice
Consider a small media-production company.
It has:
- 2 TB of active editing footage
- 15 TB of completed projects
- 40 TB of older source footage
- 60 TB of long-term backups
Putting everything on high-performance SSDs would provide excellent access speeds, but much of the capacity would rarely benefit from that performance.
A tiered design could instead look conceptually like this:
Tier 1 — Fast storage
Current editing projects and active production files.
Tier 2 — Capacity storage
Completed projects that are occasionally revisited.
Tier 3 — Cold or archival storage
Older material that needs to be retained but is rarely accessed.
Separate backup strategy
Copies designed for recovery rather than ordinary day-to-day access.
The key detail is that backup is not simply another performance tier. A storage system can move data to cheaper media and still need independent backup and recovery planning.
Why SSDs are not automatically the answer
SSDs are attractive because they provide fast access and low latency compared with traditional hard disc drives for many workloads. That makes them particularly useful for workloads that perform frequent random access or require responsive storage. But faster storage does not automatically produce a faster overall system.
If an archive is accessed once every six months, putting it on the fastest available storage may provide little practical benefit. The storage may spend almost all of its life holding data that nobody is requesting. This is where capacity-orientated storage can make more economic sense.
The decision is therefore not:
SSD = good, HDD = bad
It is:
What characteristics does this workload actually require?
A database and a photo archive illustrate the difference.
Consider two hypothetical datasets.
Dataset A: an active database
The database is constantly receiving and retrieving information.
Storage latency may affect its performance:
- Storage latency
- Random I/O
- Queue depth
- Read/write patterns
- Memory caching
- CPU performance
- Database configuration
Fast storage can therefore be valuable.
Dataset B: an old photo archive
The archive contains thousands of completed projects. It may be searched occasionally, but most files remain untouched for months.
Here, capacity and cost may matter more than extremely low latency. Both datasets are “storage”. Their requirements are simply different. That is the central idea behind tiering.
Tiering can happen automatically.
Storage tiering does not always require an administrator to move files manually. Some storage platforms can monitor access patterns and automatically move data between storage tiers according to configured policies.
A simplified policy might say:
- Frequently accessed → faster tier
- Less frequently accessed → capacity tier
- Inactive for a long period → colder tier
When the data becomes active again, the system may move or promote it back toward faster storage, depending on the technology. This can be useful because data behaviour changes. A project might be inactive for six months and then suddenly become important again. Automated tiering attempts to respond to those changing patterns rather than relying on a permanent classification.
However, automatic movement introduces its own considerations. Administrators need to understand how quickly data can move, whether movement consumes network or storage resources, and what happens when many datasets suddenly become active.
The hidden cost of moving data
It is tempting to think that moving data between tiers is free. It isn’t.
A storage system may need to:
- Identify data that qualifies for movement.
- Copy or migrate the data.
- Update metadata or mappings.
- Verify the operation.
- Potentially remove the original copy.
- Move the data again later if its access pattern changes.
Those operations consume resources. If a workload constantly switches between hot and cold states, aggressive automated tiering can become counterproductive.
For example, imagine a dataset that users access every few days but that the system classifies as cold after a short period. The system may repeatedly move it to slower storage and then bring it back. The result could be unnecessary movement without delivering much meaningful savings. A good tiering policy therefore needs to account for data behaviour over time, not just a single access event.
Storage tiering is different from caching.
The two concepts are related but should not be confused.
A cache generally keeps frequently needed copies of data in a faster location, allowing it to serve future requests more quickly. Tiering determines where the underlying data should reside among different storage levels. A system can use both.
For example:
Large capacity storage → caching layer → application
The cache may keep frequently requested information close to the application while the larger dataset remains on a capacity tier. This distinction becomes important when evaluating storage architectures. Adding a cache does not necessarily eliminate the need for appropriate underlying storage placement.
What happens when “cold” data suddenly becomes important?
This is one of the most practical questions about tiered storage. Imagine an employee opens a project that has not been touched for three years. If that project is stored on a slower tier, the initial access may take longer than it would from high-performance storage. That is not necessarily a failure.
It is part of the trade-off that made the lower-cost tier appropriate in the first place. The important question is whether the delay is acceptable. If the employee now needs the project every day, the access pattern has changed. A tiering system may eventually move the data toward a faster tier, or an administrator may do so manually.
This illustrates an important principle:
A storage tier is a policy decision, not a permanent judgement about the value of the data.
Tiering should not replace backups.
This distinction deserves special attention. Suppose a company moves old files from SSD storage to a large HDD array. The files still exist, but there may be only one copy.
If the storage array fails, the tiering strategy does not provide recovery. Likewise, moving information to an inexpensive archival service does not automatically make that information backed up.
A resilient storage strategy should separately consider:
- Primary storage
- Backup copies
- Recovery requirements
- Retention periods
- Failure scenarios
- Restoration testing
Tiering answers where data should normally live.
Backup answers how the organisation will recover it when something goes wrong.
Those are different questions.
A better way to design storage tiers
Rather than starting with a shopping list of SSDs and HDDs, start with a data inventory.
For each major dataset, record:
| Question | Example |
|---|---|
| What is it? | Active project files |
| How often is it accessed? | Several times per day |
| What response time is needed? | Interactive |
| How large is it? | 4 TB |
| How quickly does it grow? | 200 GB/month |
| Can it be regenerated? | No |
| How long must it be retained? | 5 years |
| What happens if unavailable? | Production stops. |
Then compare that information against available storage options.
This approach prevents an expensive mistake: buying high-performance storage for data that does not actually require high performance.
It also prevents the opposite mistake—putting operationally important data onto a tier whose performance or availability is inadequate.
When tiering becomes especially useful
Storage tiering tends to become more valuable as the amount and diversity of data increase.
It can be particularly useful when an environment has:
- Large datasets
- Significant differences in access frequency
- Expensive high-performance storage
- Long retention requirements
- Rapidly changing data activity
- Multiple storage technologies
- Predictable hot and cold workloads
A home user with a few hundred gigabytes of personal files may not need a sophisticated automated tiering system. A business managing tens or hundreds of terabytes may have a much stronger reason to separate frequently used information from long-term data. The right level of complexity should match the problem.
The real goal is not “fast storage everywhere”.
Storage tiering is sometimes presented as a way to save money, and cost is certainly part of the equation. But the broader goal is using storage resources according to actual workload requirements.
- Fast storage is valuable when fast access matters.
- High-capacity storage is valuable when capacity matters more than latency.
- Archival storage is valuable when long-term retention matters more than frequent access.
- A well-designed system recognises those differences instead of treating every byte as if it has identical requirements.
- That is why storage tiering is best understood as a data-placement strategy.
- The question is not simply where the data can be stored.
It is where the data should be stored given how it is used, how quickly it must be available, how much it costs to retain, and what happens if it is lost.
A simple decision framework
When evaluating a dataset, work through this sequence:
1. Is the data actively used?
If yes, consider a performance-orientated tier.
2. Does it require low-latency access?
If yes, prioritise storage capable of meeting that requirement.
3. Is it accessed occasionally rather than continuously?
A capacity-orientated tier may be sufficient.
4. Is it rarely accessed but still required?
Consider cold or archival storage.
5. Can the data be recreated?
If not, make sure the storage strategy is accompanied by appropriate backup and recovery measures.
6. Does its access pattern change over time?
If so, automated or policy-based tiering may be useful.
This framework is more useful than simply asking which storage technology is “best”.
The key idea to remember
Storage tiering works because data does not have a single, permanent performance requirement. A newly created project may be hot today, warm next month, and cold next year. A database may remain hot for its entire operational life. An archive may be almost completely inactive but still needs to remain available.
Those differences create an opportunity to use multiple storage media intelligently. Instead of paying for maximum performance across the entire dataset, a tiered system reserves faster and often more expensive storage for workloads that can actually benefit from it, while placing less demanding information on higher-capacity or lower-cost tiers. The most useful storage architecture is therefore rarely the one with the fastest hardware everywhere. It is the one that matches the storage medium to the job the data is actually doing.