CPU Scheduling and How Operating Systems Distribute Work Across Processors
A modern computer can have dozens of programs open while appearing to respond instantly to mouse clicks, keyboard input, background updates, downloads, and other work. That does not happen because every program gets a processor core permanently assigned to it.
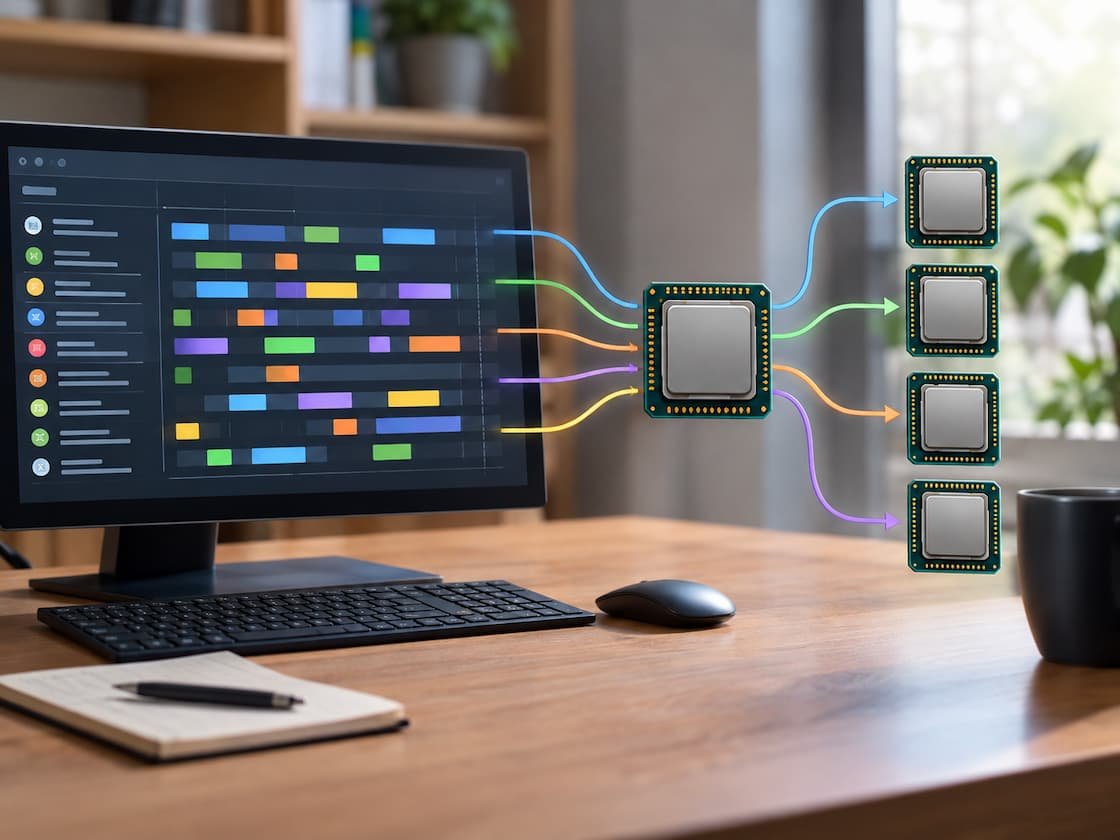
Instead, the operating system continually decides which runnable threads should use available processors, when they should run, and when another thread should take their place. This process is called CPU scheduling.
Understanding CPU scheduling also clears up several common misconceptions. A process is not necessarily the thing that directly occupies a CPU core; a computer with eight cores cannot necessarily run every part of one application simultaneously, and moving a workload between cores is not simply a matter of “giving it another core”. The scheduler has to balance responsiveness, fairness, processor utilisation, priorities, power consumption, and the characteristics of the workload.
What the operating system actually schedules
The first distinction to understand is between a process and a thread. A process provides an environment and resources for a running program. It can contain one or more threads. A thread is the execution unit that the operating system can schedule on a processor. Microsoft, for example, describes a thread as the basic unit to which processor time is allocated in Windows.
Imagine a web browser with several independent activities:
- One thread handles user-interface work.
- Another processes network activity.
- Another may decode media.
- Other threads perform background tasks.
The operating system does not generally say, “The browser gets Core 3.” It considers the browser’s runnable threads along with runnable threads belonging to other applications and system services. That distinction becomes especially important on multicore systems.
How CPU scheduling works on a multicore computer
Suppose a computer has four logical processors and twelve runnable threads. Only four threads can execute at the same instant on those four logical processors. The remaining runnable threads must wait until they can run.
A simplified sequence might look like this:
| Moment | Processor 1 | Processor 2 | Processor 3 | Processor 4 |
|---|---|---|---|---|
| A | Thread A | Thread B | Thread C | Thread D |
| B | Thread E | Thread B | Thread F | Thread D |
| C | Thread E | Thread G | Thread F | Thread H |
The actual scheduler is considerably more sophisticated than this example. It considers priority, processor availability, affinity, scheduling policy, workload behaviour, and other operating-system-specific factors. The key idea is that multiple processors provide more opportunities for simultaneous execution, while the scheduler determines which runnable threads receive those opportunities.
Windows documentation describes processor time-sharing and explains that the dispatcher makes scheduling decisions using factors including priority, processor affinity, quantum, and thread state.
Why a program can use more than one CPU core
A common misunderstanding is that an application automatically becomes faster when a computer has more cores. It doesn’t. A single-threaded workload generally has only one main stream of execution that can occupy one logical processor at a time. More cores become useful when the application can create multiple runnable threads that can perform useful work concurrently.
For example, consider an application processing 100 independent images. If it processes them sequentially, the workload might look conceptually like:
Image 1 → Image 2 → Image 3 → Image 4
A multithreaded implementation could divide independent work among several threads:
Thread A: Images 1–25
Thread B: Images 26–50
Thread C: Images 51–75
Thread D: Images 76–100
The operating system can then schedule those threads on available processors. There is a catch: dividing work introduces overhead. Threads may need to communicate, synchronise, access shared data, or wait for slower operations. If four threads spend much of their time waiting on one another, adding more processors does not provide a proportional speed improvement. This is why CPU core count and application performance are related but not interchangeable concepts.
What happens when a thread stops running?
A running thread does not necessarily remain on a processor until its task is completely finished.
A scheduler may switch execution to another thread because:
- A higher-priority thread becomes ready.
- The current thread’s scheduling opportunity expires.
- The current thread blocks while waiting for I/O or synchronisation.
- The operating system needs to make another scheduling decision.
- A different scheduling policy calls for another runnable thread.
The transition involves a context switch. The system preserves the execution state of the outgoing thread and restores the state needed by the incoming thread. Microsoft’s documentation describes a context switch as saving the outgoing thread’s context, selecting another ready thread, restoring its context, and resuming execution. Context switching makes multitasking possible, but it is not free. Excessive switching can add overhead and can also interfere with CPU-cache locality. That is one reason operating systems do not simply switch between every runnable thread as frequently as possible.
Preemptive scheduling keeps one program from taking over.
Modern general-purpose operating systems use forms of preemptive multitasking. In practical terms, the operating system can interrupt a running thread and schedule another one rather than requiring every application to voluntarily give up the processor. This is important for responsiveness.
Imagine a background application performing an intensive calculation while you move the mouse or type into another program. Without an effective preemptive scheduler, the calculation could monopolise the processor for an inconveniently long period.
Windows, for example, uses preemptive multitasking and schedules threads rather than treating the process itself as the directly scheduled execution unit. Preemption does not mean every thread receives identical treatment. Scheduling priorities and policies influence which runnable work gets processor time.
Scheduling priority changes who gets CPU time first
Operating systems can assign different priorities to threads or tasks. In Windows, scheduling priority is one of the factors used when determining which executable thread receives processor time. Threads at the highest applicable priority level are considered before lower-priority threads.
This allows an operating system to distinguish between different kinds of work.
For example:
- Interactive work may need low latency.
- Background indexing can tolerate delays.
- A system service may have requirements different from a user application.
- Time-sensitive workloads may use specialised scheduling policies.
Priority does not mean that a high-priority task receives an entire processor permanently. It affects scheduling decisions within the operating system’s scheduling model. It is also why manually raising application priority is not a universal performance solution. Giving one workload more scheduling preference can reduce the processor time available to other work.
CPU scheduling is not simply round-robin.
“Round-robin scheduling” is often used as a simple explanation of CPU scheduling because it is easy to visualise: give one task some time, then another, and then another. Real operating systems are more complicated. Different operating systems use different scheduler designs and scheduling classes. Even within one operating system, different workload types can be handled differently. For example, Linux’s scheduler documentation describes multiple scheduling classes and policies. Linux has also been transitioning its general scheduling design from the older Completely Fair Scheduler (CFS) toward EEVDF — Earliest Eligible Virtual Deadline First.
The Linux documentation describes EEVDF as using virtual runtime and virtual deadlines to determine which eligible task should execute, with the design intended to distribute CPU time fairly while also accounting for latency-sensitive work. So when explaining “the CPU scheduler”, it is more accurate to discuss the general principles rather than implying that Windows, Linux, and other operating systems all use the same algorithm.
How work gets distributed across processor cores
On a multicore system, scheduling has another problem: which processor should run a particular thread?
If one processor is overloaded while another is relatively idle, the operating system may redistribute runnable work. This is commonly described as load balancing. But moving a thread is not always beneficial. Processors have caches that contain recently used instructions and data. If a thread moves between processors, some of the useful cache locality associated with its previous processor may be lost.
The scheduler therefore has to balance competing considerations:
| Scheduling concern | Why it matters |
|---|---|
| Load balancing | Prevents some processors from sitting idle while others are overloaded |
| Processor affinity | Can keep work associated with selected processors |
| Responsiveness | Helps interactive tasks receive timely CPU access |
| Fairness | Prevents runnable work from being indefinitely neglected |
| Cache locality | Avoids unnecessary movement when staying on a processor is beneficial |
| Power efficiency | Can matter significantly on laptops and mobile systems |
| Priority | Allows time-sensitive or important work to receive appropriate scheduling treatment |
Modern operating systems can therefore make sophisticated decisions rather than simply assigning each new task to the least-used core.
Processor affinity: when a thread is restricted to certain CPUs
Processor affinity refers to limiting where a thread or process can execute. There are legitimate reasons for doing so. Specialised software may benefit from controlling which processors handle particular workloads, and some applications need predictable processor placement.
But affinity can also become counterproductive. Suppose a computer has eight logical processors, but a CPU-intensive application is restricted to two of them. The other six processors may have available capacity while those two become heavily loaded.
Windows provides affinity-related mechanisms as well as newer CPU Set APIs. Microsoft notes that affinity decisions can affect overall system performance, particularly when they interfere with other work. For ordinary desktop users, manually restricting CPU affinity is therefore not automatically an optimisation.
What happens when a CPU-heavy task is running?
Consider a video export running in the background while you browse the web. The export may have several worker threads doing computational work. Your browser may also have runnable threads, while the operating system has its own work to perform.
A simplified scheduling cycle looks like this:
- The operating system tracks runnable threads.
- Available processors are evaluated.
- The scheduler selects appropriate runnable threads.
- Selected threads execute.
- Some threads finish, block, yield, or are preempted.
- Scheduling decisions are made again.
- Work may be redistributed as processor availability changes.
This happens continuously. The result is that a computer can feel responsive even while its processors are handling a large amount of background computation.
Why 100% CPU usage does not automatically mean something is wrong
High CPU utilisation simply means that the processors are spending a large amount of time executing work. If you deliberately start a computationally intensive task, sustained high CPU usage can be completely normal. The more useful question is what is consuming the CPU and whether the resulting performance is acceptable.
For example:
- A video encoder using nearly all available CPU during an export may be expected.
- An idle computer repeatedly reaching very high CPU usage deserves investigation.
- A game using substantial CPU while maintaining stable performance may not indicate a problem.
- A background task consuming CPU and making the entire system unresponsive may indicate a scheduling, resource, or workload issue worth investigating.
CPU utilisation should therefore be interpreted alongside responsiveness, application performance, temperatures, power consumption, and the identity of the workload.
CPU scheduling versus CPU utilisation
These concepts are related but not identical.
- CPU scheduling is the process of deciding which runnable work gets processor time.
- CPU utilisation describes how much processor capacity is actually being used.
A computer can have sophisticated scheduling but still show low CPU utilisation if most tasks are waiting for storage, network activity, user input, or other resources. Likewise, high utilisation does not necessarily mean scheduling is inefficient. The workload may simply have enough useful computation to keep the available processors busy. This distinction helps when diagnosing a slow computer: looking only at the CPU percentage can miss the real bottleneck.
What users should take away from CPU scheduling
The simplest useful mental model is this:
Applications create processes and threads; the operating system schedules runnable threads onto available logical processors; scheduling decisions change continually as priorities, workload states, processor availability, and system conditions change.
More CPU cores give the operating system more execution capacity, but they do not automatically speed up every application. The application must have work that can use multiple execution threads, and the scheduler still has to coordinate those threads with everything else running on the system. CPU scheduling is therefore less about “giving each program a core” and more about continuously coordinating competing streams of work on limited processor resources. That coordination is one of the fundamental reasons a modern operating system can make a computer appear to run many things simultaneously while still maintaining control over processor resources.
Conclusion
CPU scheduling is the operating system’s ongoing method for coordinating processor time among runnable threads. On a multicore computer, the scheduler also has to decide where that work should run while balancing responsiveness, fairness, processor utilisation, cache locality, priorities, and other system requirements.
Once you understand that threads—not entire applications—are the fundamental units being scheduled, multicore performance becomes much easier to reason about. More cores provide more opportunities for parallel execution; the scheduler determines how those opportunities are used.
FAQs
1. Does the operating system schedule processes or threads?
The practical answer is threads. A process provides the environment and resources in which threads execute, while the scheduler selects runnable threads for processor execution.
2. Can two threads from the same program run at the same time?
Yes. If an application has multiple runnable threads and sufficient processor capacity is available, different threads can execute concurrently on different logical processors.
3. Does having more CPU cores always make a computer faster?
No. Additional cores can increase available parallel execution capacity, but the improvement depends on whether the workload can effectively use multiple threads and whether other bottlenecks limit performance.
4. What is a context switch?
A context switch occurs when the system stops one thread’s execution and switches the processor to another thread, preserving and restoring the relevant execution state as necessary.
5. What is CPU affinity?
CPU affinity is a mechanism for restricting or influencing which processors a thread or process can run on. It can be useful in specialised circumstances but may hurt performance if applied unnecessarily.